Activity (50)
Course (40)
Glossary Term (1030)
Insight (765)
Certification (91)
Collection (313)
Session (2327)
Moment (7135)
Newsletter Issue (359)
News (412)
Link (4231)
Solution (81)
SWAG (Scientific Wild Ass Guess): A high-level estimation technique used by 'Heads Of' and Test Managers of various levels, to provide an early indication of testing effort, duration, resource requirements, cost, or scope when detailed requirements, plans, or designs are not yet available. SWAG estimates are based on professional experience, historical delivery data, expert judgement, assumptions, and known risks rather than detailed analysis.
SWAG estimation asks: "Based on what we know today, what is a reasonable estimate?" Test Managers use SWAG estimates to support early planning, budgeting, resourcing, release forecasting, and stakeholder discussions. The goal is to provide a pragmatic indication of the likely testing demand while acknowledging uncertainty and potential change. Often used in Annual or Quarterly planning of incoming work.
This is the step before detailed test estimation, where it asks: "What can we accurately forecast based on defined scope and evidence?" Estimates are created using detailed requirements, test scope, complexity assessment, dependencies, resource availability, environments, defect history, and delivery schedules. The goal is to provide a more accurate and reliable forecast for planning and delivery commitments.
A SWAG estimate should not be treated as a delivery commitment. It is intended to inform decision-making and facilitate planning conversations until sufficient information is available to produce a detailed and evidence-based test estimate. As scope, requirements, and delivery plans mature, SWAG estimates should be reviewed, refined, and replaced with more accurate forecasts.
Static analysis is examining the code without executing it; providing understanding of code structure and ensuring the code adheres to industry standards (~4 mins)
CVE, short for Common Vulnerabilities and Exposures, is a list of publicly disclosed computer security flaws. The CVE system works by assigning unique, standardized identification numbers to publicly disclosed software vulnerabilities so organizations can track and share security information across different tools and databases.CVE entries are brief. They don’t include technical data or information about risks, impacts, and fixes. Those details appear in other databases, including the U.S. National Vulnerability Database (NVD), the CERT/CC Vulnerability Notes Database, and various lists maintained by vendors and other organizations.
What qualifies as a CVE?According to the CVE Numbering Authority operational rules, CVE IDs are assigned to flaws that meet specific criteria. Flaws must:
Be independently fixable. The flaw can be fixed independently of any other bugs.
Be acknowledged by the affected vendor or documented. The software or hardware vendor acknowledges the bug's existence and confirms that it negatively impacts security. Alternatively, the reporter must have shared a vulnerability report that demonstrates both the negative impact of the bug and that it violates the security policy of the affected system.
Affect only 1 codebase. If a flaw impacts more than 1 product, it gets a separate CVE for each product. In cases of shared libraries, protocols or standards, the flaw gets a single CVE only if there’s no way to use the shared code without being vulnerable. Otherwise each affected codebase or product gets a unique CVE.
A Sprint Review is a collaborative session near the end of a Sprint where the team and stakeholders inspect what has been delivered, gather feedback and discuss what should happen next. For testers, it is also an opportunity to share testing insights, learn more about how the product will be used, identify assumptions and discover new areas of risk.
If you ask an AI model, "I need to get my car cleaned, and the car wash is 100 metres away, should I walk or drive?", several popular LLMs tell you to walk. They give you a well-written breakdown on saving petrol, squeezing in a quick bit of exercise, and avoiding the hassle of starting an engine for a short trip.It sounds sensible, until you remember the physical reality: walking 100 metres leaves your dirty car sitting in the driveway.The model isn't reasoning. It catches keywords like "100 metres", "walk", and "drive", and immediately routes down a path of health and environmental advice. It completely misses the actual goal because it lacks a basic mental model of how the physical world fits together.
One run of the test. A pass only proves that one run.
What is a Steel Thread?A thin, end-to-end slice that runs through every layer of the system - proving the whole path works before you widen it.For example, one Jira test travels the full pipeline - exported, built into an Al journey, executed, and reported - automatically.
Continuous performance testing means regularly asking:
“Can this system stay fast, reliable, and usable when real people use it?”It means running performance tests throughout the software development cycle and after release, rather than testing only once before launch.
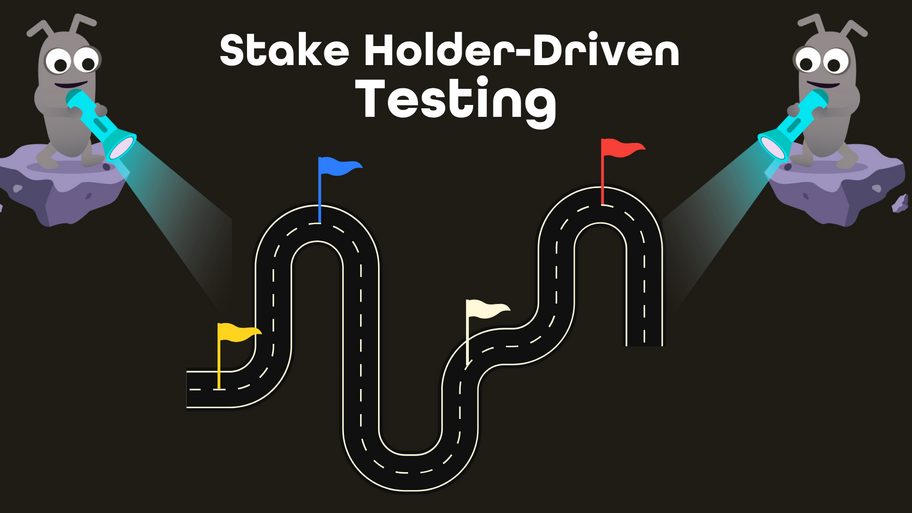
Stakeholder-Driven Testing: A testing approach in which test scope, priorities, scenarios, and acceptance criteria are shaped by the needs, risks, expectations, and business goals of key stakeholders, ensuring testing focuses on the outcomes that matter most to users, customers, sponsors, and operational teams.Stakeholder-Driven Testing asks: "What matters most to stakeholders?" specifically. Testing is prioritised according to stakeholder needs, concerns, expectations, and objectives. The goal is to provide confidence in the areas stakeholders consider most important.Risk-Based Testing asks: "What could go wrong?" which can involve stakeholder input but - Testing is prioritised according to the likelihood and impact of risks. The goal is to focus effort where failures would cause the greatest business, technical, operational, or compliance impact.However, stakeholders may also prioritise areas that are not high risk but (said in a Scottish accent) are high visibility, strategically important, or critical to user/player experience.See also: Stakeholder (in Software Development) | MoTaverseRisk-based testing | MoTaverse
Definition: An interactive programming environment that reads a single input, evaluates it, prints the result, then loops back to wait for the next input. It lets you run code a piece at a time rather than compiling and running a whole program.So what? A REPL gives immediate feedback, which makes it handy for exploratory coding, quick debugging, and confirming how a snippet behaves before committing to it.Examples: Typing node in a terminal to open the Node.js REPL and running expressions line by line; using Python's interactive shell to try a function before adding it to a test.
Definition: An open-source toolkit from GitHub for spec-driven development with AI coding agents. It provides a CLI, templates and prompts that move work through defined phases (specify, plan, tasks, then implement), treating the specification as the source of truth that the AI builds against. It is tool-agnostic and works with agents such as GitHub Copilot, Claude Code and Gemini CLI.So what? It aims to move teams beyond ad-hoc "vibe coding" towards a repeatable, verifiable workflow, so an AI agent builds what was intended rather than a generic solution based on common patterns.Example: Using slash commands such as /specify, /plan and /tasks to turn a written specification into a technical plan and a set of small, testable tasks for an AI agent to implement.
Definition: An open-source framework for building software with AI, using specialised agent personas (such as Analyst, Product Manager, Architect, Developer and QA) that work through structured, phase-by-phase workflows mirroring a real engineering team. It defines what each agent does and what artefacts they produce, and can sit alongside existing agile approaches like Scrum or Kanban rather than replacing them.So what? It brings agile structure and documentation to AI-assisted development so outputs are more repeatable and context carries forward between phases, addressing a common failure point where intent is lost across a long conversation.Example: A planning phase produces specifications that are then split into self-contained story files, each carrying the requirements, constraints and acceptance criteria a Developer or QA agent needs to complete that unit of work.
Team of 5 or fewer? TestRail now starts at $22/user. Test case management, defect integrations, reporting, and more.
Take this 7-question assessment to see where your QA team stands and get a plan for what to automate next.
BearQ continuously tests your app, reducing test maintenance and uncovering gaps scripted tests can miss.
Getting tests that catch real failures is the hard part. Watch the recording now on demand!
